What Is Jev? TypeSafe's System One Model Explained
2026-09-21
Jev is TypeSafe's System One model: typed probabilities in, no text out. Here's how it works, what it costs, and where the zero-hallucination claim stops.
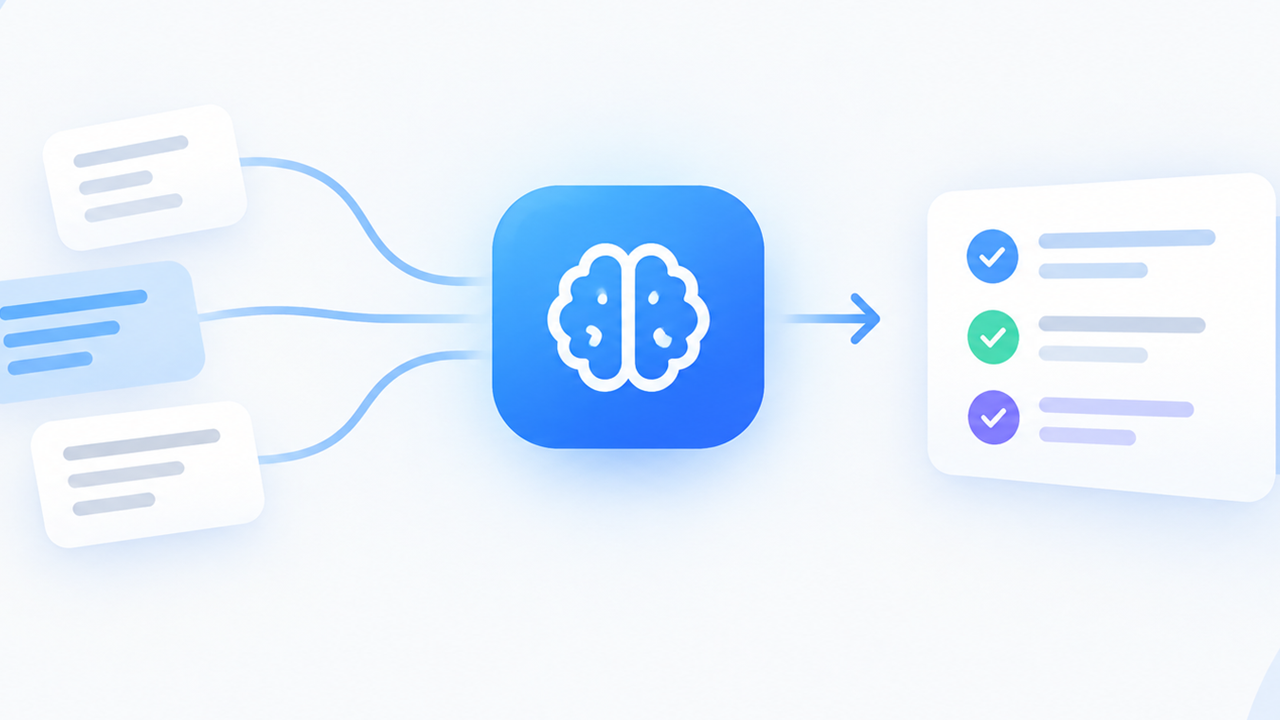
TypeSafe AI came out of stealth on September 15, 2026, with something that isn't a chatbot. Jev, the lab's first public System One model, doesn't write sentences. It takes messy input and returns typed, calibrated decisions that your code can read directly.
That puts Jev AI in an unusual spot. Everyone else has spent two years shipping systems that talk, and TypeSafe shipped one that stays quiet and decides.
That's a strange pitch in a year full of chat assistants, so it's worth unpacking what a System One model actually is, what Jev does differently, and whether any of it matters to you as someone who uses apps and tools every day.
Why should you care about a model that can't write a sentence? Because most of the AI you already depend on is quietly making decisions, not chatting, and Jev is the first model aimed squarely at that.
What Jev Is: A Decision Model, Not a Chatbot
Jev is a model that answers questions with structured values instead of text.
The framing TypeSafe uses is simple: think of it as a frontier-intelligence function call. Unstructured state goes in, typed probabilistic decisions come out. There's no prose, no explanation paragraph, no chance the model drifts off topic mid-answer.
For anyone building Android or web software, that's the interesting part. A chatbot has to be read by a human. A decision model can be read by code. When your app needs to know "is this message a refund request," you don't want a paragraph. You want a yes or no with a confidence score attached.
How Jev's System One Model Works
The name comes from Daniel Kahneman's Thinking, Fast and Slow. System 1 thinking is fast and intuitive. System 2 is slow and deliberate. Jev sits squarely in the first category, built for quick, focused judgments inside larger workflows.
Mechanically, you send Jev a state and a set of typed questions. The state is whatever context matters: a customer message, transaction records, a policy document. The questions are constraints you define in advance. Jev evaluates everything and returns answers with probabilities, all in a single pass.
That single pass is where the speed claim comes from. Regular LLMs generate one token at a time, each conditioned on the last, which is why they feel slow. Jev generates all its outputs in parallel at once. TypeSafe says end-to-end response time lands between 70ms and 500ms, against 3 to 329 seconds for frontier LLMs.
The Primitives Behind Jev Decisions
You don't ask a Jev model in free-form language. You ask through primitives, which are pre-defined answer spaces.
Three matter most. Choice asks a multiple-choice question, like which team should handle a support ticket, with a fixed list of options. Score asks for a value on a scale, like how frustrated a customer sounds between calm and very frustrated. Noul, the odd name of the set, asks a boolean question such as whether a message requests a refund.
The output structure never varies. A Choice question returns an option string. A Score question returns a number. A Noul question returns a probability.
That constraint is the whole design. The possible answers are defined in advance, so Jev can't invent a field or return a value outside your schema. TypeSafe calls this type safety, and the company says type errors are mathematically impossible.
Why Jev's Zero-Hallucination Claim Is Narrow
TypeSafe states plainly that Jev can't hallucinate. Read that carefully, because it means something more specific than it sounds.
Jev can't return a value outside the answer space you gave it. If you ask which of three teams should get a ticket, it will return one of those three teams every time. That eliminates malformed output, invented fields, and made-up options.
What the claim doesn't cover is judgment. Jev can still return a perfectly valid answer that happens to be wrong. If the model scores a calm customer as very frustrated, that's a wrong call wrapped in a clean integer. The type is correct; the read is off.
The confidence scores help here. Every Jev output ships with calibrated probabilities, which means a higher confidence number should track with higher accuracy across many predictions. Calibration is measured in groups, so it doesn't guarantee any single answer is right. It tells you when to trust the result and when to escalate to a person.
Jev Pricing and Speed Compared With LLMs
The cost story is where Jev gets genuinely hard to ignore.
Jev charges $0.042 per million input tokens. Output tokens are free. TypeSafe's framing is that outputs are too cheap to meter, since the model isn't generating long strings of text. Compare that with frontier LLMs, which run from $0.20 to $10 per million input tokens and charge roughly five times more for output.
In plain numbers, high-volume classification that would burn real money on a chat model costs pennies on Jev. A workload handling ten thousand requests a month can land in the low single digits of dollars.
Speed works the same way. TypeSafe claims Jev is two orders of magnitude faster and more efficient than existing LLMs on System One style tasks. Skeptics should note that the boldest of those figures are self-reported and run from TypeSafe's own West Coast machines.
Where Jev Fits in Real Software
The practical use cases are less glamorous than chat, and more useful.
Think about agent routing: an app that decides which tool an AI agent should call next before it burns a slow LLM call on the wrong path. Or data work, where you map-reduce across terabytes and need a fast, consistent scorer at every step. Or real-time apps, where a 100ms decision is the difference between a feature that works and one that doesn't.
There's also verification. Jev can score, judge, or flag LLM outputs, including detecting jailbreak attempts. That's a job where you want a fast pass or fail, not a thoughtful essay. Every one of these tasks is a place where hand-written if-statements are too brittle and full LLMs are overkill, which is exactly the gap TypeSafe is aiming at.
JevBench, the Playground, and What's Still Unverified
Less than a week after launch, two more Jev items surfaced: a Jev Playground for testing the model interactively, and JevBench, which TypeSafe describes as the first benchmark built for decision models. Jev reportedly leads it with a score of 75.3.
Worth a skeptical read. A vendor topping its own leaderboard is expected, not surprising. And TypeSafe's headline claims have moved in odd ways, from "up to 400x cheaper" at launch to a reported 440x days later, with no published explanation of how either figure was measured. Reasonable people can treat those multipliers as marketing anchors rather than measurements.
None of that makes JevBench useless. Before it, decision models had no dedicated eval at all, so a purpose-built benchmark is a real contribution even if it's self-published. You just shouldn't treat the ranking as an independent verdict.
Is Jev Worth Paying Attention To?
Yes, if you build software. Jev isn't competing with the chat assistant you talk to on your phone. It's competing with the fragile, hand-written rules inside apps that decide things.
Not a chatbot. Not a drafting tool. A fast, narrow judge that lives inside your code.
If you're a regular Android user, Jev is the kind of tool you'll meet indirectly. It's the fast layer that routes your support ticket, scores your app review, or decides whether your booking needs a human. You won't see it, and that's the point.
TypeSafe's founder Diogo Almeida helped build the methods behind ChatGPT at OpenAI before betting that the next gap is automation, not conversation. Jev is his answer. Whether the multipliers hold up under independent testing is the open question, and it's one worth watching as more teams put the model through real workloads.
You can try the Jev Playground to see typed decisions in action, install the TypeSafe SDK, or read the docs and connect the Jev API to your own project. Either way, start with one small decision task and check the confidence scores before you trust the model with anything that matters.
You can also check other ai tool:

 NEWS
 REVIEWS
 HOWTO